
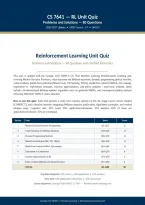
CS 7641 — RL Unit Quiz
Problems and Solutions — 80 Questions
2026/2027 Update • 100% Correct - GT • OMSCS
Reinforcement Learning Unit Quiz
Problems and Solutions — 80 Questions with Verified Rationales
This quiz is aligned with the Georgia Tech OMSCS CS 7641 Machine Learning Reinforcement Learning unit,
covering Markov Decision Processes, value functions and Bellman equations, dynamic programming (policy iteration,
value iteration), model-free prediction (Monte Carlo, TD learning, TD(λ)), model-free control (SARSA, Q-Learning),
exploration vs. exploitation strategies, function approximation, and policy gradient / actor-critic methods. Items
include calculation-based Bellman updates, algorithm traces on gridworld MDPs, and convergence/stability analysis
reflecting 2026/2027 OMSCS course structure.
How to use this quiz: Each item presents a stem, four response options (A–D), the single correct answer marked
[CORRECT], and a detailed rationale integrating Bellman equation justification, algorithmic principles, and worked
solution steps. Cognitive mix: 25% recall, 50% application/calculation, 25% analysis. 65% of items are
application/calculation; 35% are conceptual.
Section Topic Items Count
1 Markov Decision Processes Fundamentals Q1–Q12 12
2 Value Functions and Bellman Equations Q13–Q24 12
3 Dynamic Programming Methods Q25–Q38 14
4 Model-Free Prediction (MC, TD, TD(λ)) Q39–Q50 12
5 Model-Free Control (SARSA, Q-Learning) Q51–Q62 12
6 Exploration vs. Exploitation Q63–Q70 8
7 Function Approximation in RL Q71–Q76 6
8 Policy Gradient Methods and Advanced Topics Q77–Q80 4
TOTAL Q1–Q80 80
Cognitive blueprint: 25% recall • 50% application • 25% analysis
Item style: 65% application/calculation • 35% conceptual
Course alignment: Georgia Tech OMSCS CS 7641 — Reinforcement Learning Unit
Georgia Tech OMSCS • Machine Learning • Reinforcement Learning Unit
,CS 7641 — Machine Learning | Reinforcement Learning Unit Quiz Georgia Tech OMSCS • 2026/2027 Update
Section 1: Markov Decision Processes Fundamentals
States, Actions, Rewards, Transitions, and Discount Factor — Questions 1 through 12
Q1: A Markov Decision Process is formally defined by which tuple of components?
A. (S, A, P, R, γ) — states, actions, transition probabilities, reward function, and discount factor. [CORRECT]
B. (S, A, V, Q, π) — states, actions, values, action-values, and policy.
C. (S, A, E, R, T) — states, actions, episodes, rewards, and time horizon.
D. (V, Q, π, γ, P) — values, action-values, policy, discount, and transitions.
Correct Answer: A
Rationale: An MDP is the 5-tuple (S, A, P, R, γ): a set of states S, a set of actions A, transition probabilities P(s'|s,a), a
reward function R (or R(s,a) / R(s,a,s')), and a discount factor γ [0,1]. V, Q, and π are derived objects computed FROM
the MDP, not part of its definition.
Q2: The Markov property states that:
A. The future depends only on the present state, not on the history of past states. [CORRECT]
B. The future depends on the entire sequence of past states and actions.
C. Rewards are always non-negative.
D. The discount factor must be less than 1.
Correct Answer: A
Rationale: The Markov property (memoryless): P(S_{t+1} | S_t, A_t, S_{t-1}, A_{t-1}, ...) = P(S_{t+1} | S_t, A_t). The
state is a sufficient statistic of history. This is what makes the Bellman equations recursive and tractable; without it, RL
algorithms would need the full trajectory.
Q3: Which statement correctly distinguishes episodic from continuing tasks?
A. Episodic tasks have a terminal state that ends an episode; continuing tasks have no terminal state and run
indefinitely. [CORRECT]
B. Episodic tasks have no terminal state; continuing tasks always terminate.
C. Episodic tasks require discounting; continuing tasks do not.
D. Episodic tasks are stochastic; continuing tasks are deterministic.
Correct Answer: A
Rationale: Episodic tasks (e.g., a chess game, a maze) have a well-defined terminal state that ends the episode, allowing a
finite return G_t. Continuing tasks (e.g., a robot controlling a power plant indefinitely) have no natural end, so discounted
returns or average-reward formulations are needed to keep G_t finite. Both can use discounting, but continuing tasks
essentially require it.
Q4: The discounted return G_t is defined as:
A. G_t = R_{t+1} + γ·R_{t+2} + γ²·R_{t+3} + ... = Σ_{k=0}^{∞} γ^k · R_{t+k+1} [CORRECT]
B. G_t = R_t + γ·R_{t-1} + γ²·R_{t-2} + ...
C. G_t = Σ_{k=1}^{N} R_k where N is the number of states
D. G_t = max_a R(s,a) for all steps
Correct Answer: A
Rationale: The discounted return G_t = Σ_{k=0}^{∞} γ^k · R_{t+k+1} discounts future rewards geometrically by γ. With
γ < 1, the infinite sum converges for bounded reward sequences. The convention R_{t+1} (reward received AFTER taking
action at time t) is standard in Sutton & Barto. Option B is backwards in time; C is finite-sum (no discounting); D is a
one-step greedy formulation.
Problems and Solutions | 100% Correct - GT Page 2
, CS 7641 — Machine Learning | Reinforcement Learning Unit Quiz Georgia Tech OMSCS • 2026/2027 Update
Q5: Why is the discount factor γ typically set to a value less than 1 (e.g., 0.9 or 0.99)?
A. It ensures the infinite-horizon return converges to a finite value, models preference for sooner rewards, and
provides mathematical tractability. [CORRECT]
B. It guarantees that all policies are optimal.
C. It is required for the Markov property to hold.
D. It eliminates the need for exploration.
Correct Answer: A
Rationale: With γ < 1, the infinite series G_t = Σ γ^k R_{t+k+1} converges absolutely whenever rewards are bounded,
giving a finite, well-defined value function. It also models a preference for immediate reward (uncertainty about the far
future). γ does not affect the Markov property, optimality, or exploration — those are separate concepts.
Q6: In an MDP, the transition function P(s' | s, a) represents:
A. The probability of transitioning to state s' given that action a is taken in state s. [CORRECT]
B. The reward received when taking action a in state s.
C. The value of taking action a in state s.
D. The probability of taking action a in state s.
Correct Answer: A
Rationale: P(s' | s, a) is the state-transition probability: the probability of arriving in state s' after taking action a from state
s. This is the environment's dynamics and is unknown to the agent in model-free RL. R(s,a) is the reward; Q(s,a) is the
action-value; π(a|s) is the policy (probability of choosing action a in state s).
Q7: In a gridworld MDP, a robot in state s=(1,1) can move Up/Down/Left/Right. After taking action 'Up', it
ends up at (1,2) with probability 0.8 and at (1,1) (slipped) with probability 0.2. What is P(s'=(1,1) | s=(1,1),
a=Up)?
A. 0.2 [CORRECT]
B. 0.8
C. 0.5
D. 1.0
Correct Answer: A
Rationale: The problem states that with action Up from (1,1), the robot slips and stays at (1,1) with probability 0.2.
Therefore P((1,1) | (1,1), Up) = 0.2. The 0.8 corresponds to arriving at (1,2). Probabilities must sum to 1 over all possible
next states.
Q8: A stochastic policy π(a | s) is:
A. A probability distribution over actions for each state. [CORRECT]
B. A single deterministic action for each state.
C. The transition probability P(s'|s,a).
D. The reward function R(s,a).
Correct Answer: A
Rationale: A stochastic policy π(a|s) gives the probability of selecting action a in state s; Σ_a π(a|s) = 1 for each s. A
deterministic policy is the special case where π(a|s) = 1 for one action and 0 for all others. Stochastic policies enable
exploration and are essential for policy gradient methods.
Problems and Solutions | 100% Correct - GT Page 3


